
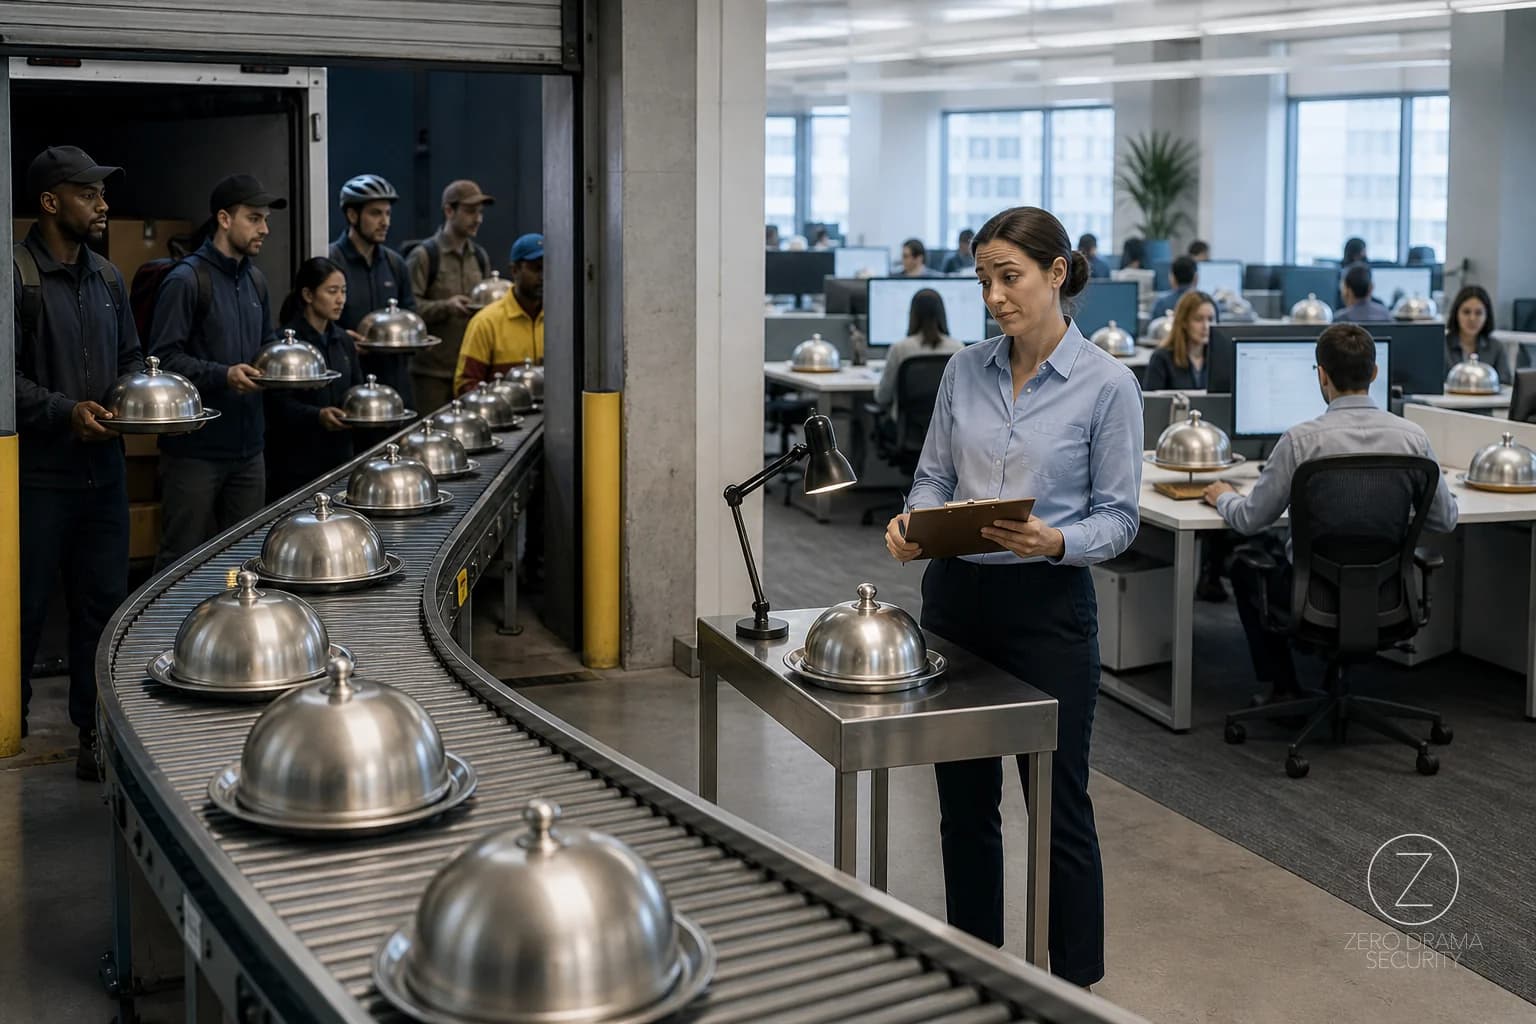
A vendor review can tell you whether a supplier looks acceptable. It does not tell you whether every AI output from that supplier deserves to enter your workflow as fact, instruction, evidence, or production state.
That distinction is getting missed.
Third-party AI risk is often treated like a procurement problem: review the vendor, inspect the contract, ask about training data, confirm security posture, file the answers. Useful work. Also incomplete.
The operational risk shows up later, when the AI vendor’s output starts moving through the business. A summary is copied into a case record. A classification changes queue priority. A recommended response goes to a customer. A risk score triggers review. An enrichment updates an account. A generated answer becomes support guidance. A tool call starts from something the model said.
At that point, the question is no longer just whether the vendor is acceptable. The question is what authority the output has.
Vendor approval is not output approval
Security teams know how to review suppliers. They are less consistent at reviewing supplier outputs as inputs to their own systems.
That gap is convenient because it lets everyone feel governed without slowing the workflow. Procurement cleared the vendor. Legal reviewed the terms. Security looked at the questionnaire. The product team integrates the API. The business gets the feature.
But an AI output is not like a static file delivered by a vendor once a quarter. It can vary by prompt, context, retrieved data, model change, customer record, user role, and workflow state. Some outputs are harmless suggestions. Some become operational instructions. Some quietly change what people believe is true.
That is why third-party AI risk needs an intake boundary, not just a vendor risk record.
The boundary decides what comes in, what it is allowed to influence, what must be checked, what gets logged, and who owns the decision when the output is wrong.
Start by classifying the authority of the output
Not every AI output deserves the same control. Treating all vendor generated content as high risk creates review theater. Treating all of it as normal application data creates avoidable exposure.
A practical model starts with authority.
Advisory outputs help a person think. A draft summary, suggested next step, or candidate explanation can be useful without being trusted as final. The control is usually disclosure, user judgment, and a way to compare against source material.
User visible outputs reach customers, employees, partners, or regulated audiences. The risk is not only whether the text is accurate. It is whether the organization is now saying it. That changes review, logging, escalation, and ownership.
System influencing outputs affect workflow state. They classify, route, prioritize, approve, deny, enrich, update, trigger, or suppress something. This is where the intake boundary matters most. The output is no longer just content. It is part of the control path.
System changing outputs create or modify records, permissions, payments, tickets, policies, messages, cases, or other business objects. At that point, you are close to the same territory discussed in AI Agent Tool Access Needs a Transaction Boundary. The model output may not be the actor, but it is helping drive the action.
The intake boundary is where validation belongs
A good intake boundary does not try to make the vendor perfect. It assumes the output may be useful, incomplete, stale, misaligned, or unsafe for a particular workflow.
The boundary should answer a few concrete questions.
What type of output is this? Free text, label, score, structured field, recommendation, command, generated document, extracted fact, or decision support all behave differently.
What source context was used? The system does not always need to retain every prompt or full source document. In many cases, retaining less is the privacy safer choice. But it does need enough evidence to understand what class of data influenced the output and what workflow accepted it. This is the same evidence tension behind AI Logging Policy: Why Most Enterprises Collect Prompts They Should Never Keep.
What is the output allowed to affect? A vendor generated risk label may be allowed to sort a queue but not deny a customer request. A summary may be allowed in an internal note but not in a customer notification. A recommendation may be allowed to prefill a form but not submit it.
What happens when confidence is low, source evidence is missing, or the output conflicts with known system data? If the answer is “the workflow continues anyway,” the model output has more authority than the governance process admits.
Who can override it, and is that override captured as evidence? Human review only counts when the human can understand, challenge, and change the result. Otherwise, it is just a pause button with a nicer label.
Evidence should prove the boundary worked
The audit record should not merely say that an AI vendor returned a response. That proves an integration ran. It does not prove the control worked.
Useful evidence is more specific. It shows the source system, output class, receiving workflow, policy checks applied, validation result, human review when required, final action taken, and override or rejection if one occurred.
This does not mean storing everything forever. In fact, broad retention of prompts, outputs, attachments, and retrieved documents can create its own privacy problem. The evidence design should separate operational proof from unnecessary content retention.
This is where many AI governance programs drift into paperwork. They can name the vendor and describe the intended use, but they cannot show how an output moved through the system or why it was trusted in a specific case. That is the same pattern described in AI Vendor Due Diligence: Why Security Reviews Keep Missing the Real Risk: reviewing the supplier is not the same as controlling the operating model.
The tradeoff is speed versus unearned trust
Teams adopt AI vendors because they want faster analysis, cleaner workflows, better triage, cheaper drafting, or more responsive customer operations. Those are legitimate goals.
The answer is not to send every model output to a committee. That would turn governance into latency with a policy wrapper.
The better tradeoff is to reserve friction for outputs with authority. Low impact suggestions can move quickly. Customer visible content gets clearer review and disclosure rules. System influencing outputs get validation, scope limits, and rejection paths. System changing outputs need transaction boundaries and stronger evidence.
That model is easier to defend because it names the risk instead of pretending all AI use is the same.
A short operating checklist
Before a third-party AI output enters a production workflow, ask:
- Is this output advisory, user visible, system influencing, or system changing?
- What workflow consumes it, and what can it change?
- What policy checks run before acceptance?
- What source context is needed for evidence, and what should not be retained?
- Who owns false positives, false negatives, bad summaries, and bad recommendations?
- Can the output be rejected, corrected, quarantined, or replayed?
- Does the audit trail show the decision, not just the API call?
If those questions are hard to answer, the integration may be moving faster than the control design.
For teams turning AI governance into working architecture rather than approval paperwork, Zero Drama Security services can help define the boundaries, evidence, and decision rights without turning the program into theater.
Vendor approval is a start. The intake boundary is where third-party AI risk becomes operational.